Start with the problem.
A general-purpose model does not automatically know a company's current policies, products or customer permissions. This study builds a governed knowledge collection and evaluates the assistant on real questions before it is used with customers or staff.
A practical way forward.
Curate the dataset
Inventory permitted documents, remove duplicates, record ownership and review dates, and organise examples of good answers and appropriate handovers.
Retrieve before answering
Use retrieval-augmented generation, or RAG, to find relevant approved material. Keep user access rules attached to the retrieved content.
Evaluate and maintain
Test answer accuracy, source support, refusal and escalation behaviour. Re-index changed material and review feedback with a named content owner.
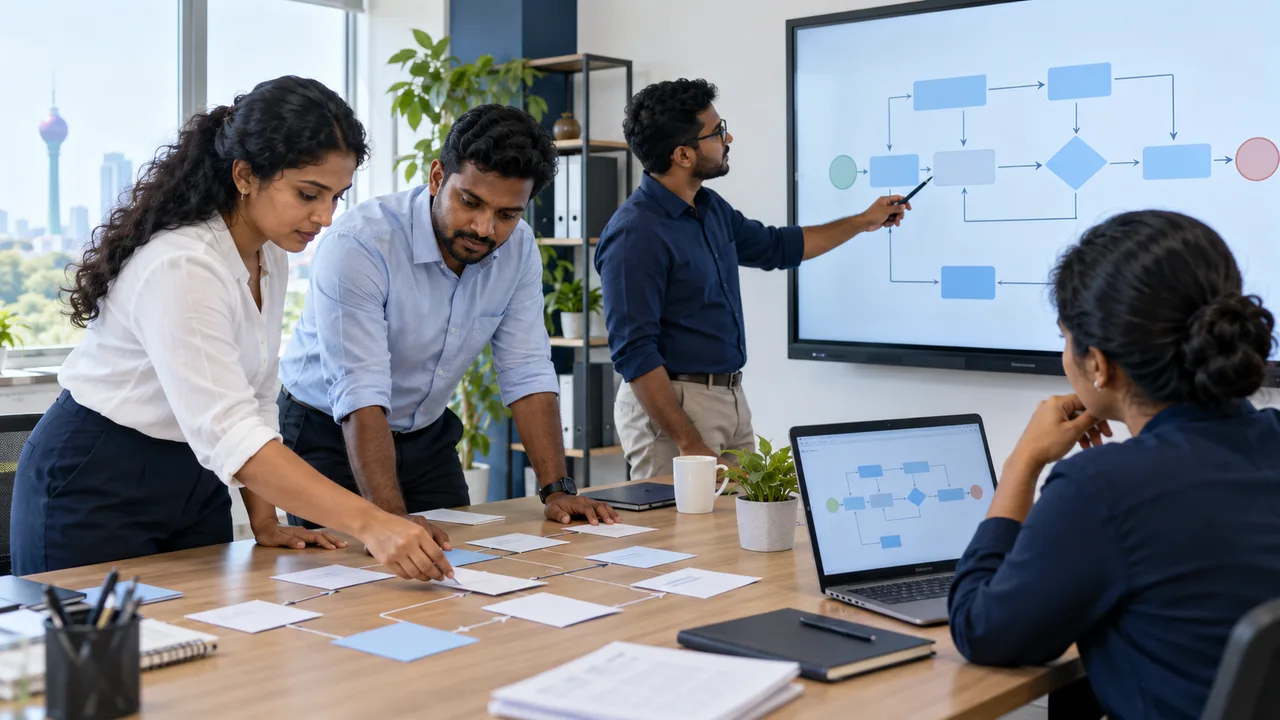
The workflow, simply.
- Approve source content
- Index with permissions
- Retrieve & answer
- Evaluate & update
Architecture to consider.
A versioned ingestion pipeline records provenance and processing history.
Search or vector retrieval applies document permissions before context reaches the model.
A chat API returns source references and routes low-confidence or unsupported requests to staff.
How success should be tested.
- Use a held-out question set with source-backed reference answers.
- Test document access boundaries and prompt-injection attempts.
- Measure unsupported-answer rate and whether handovers reach the right team.
Useful things to know.
Does a business assistant always need model training?
No. Retrieval from approved documents may solve a knowledge problem without fine-tuning. Training is considered when a defined behaviour or task needs it and suitable permitted examples are available.
What is a custom business dataset?
It is a curated, documented collection of permitted source material, labels or examples for a specific task. Useful datasets include ownership, version history, quality checks and separate evaluation examples.